The platform underneath your AI product.
One API for serving models, running agents and measuring quality. Ship in days, scale without rewrites.
EVAL · CHECKOUT-AGENT
0.94
▲ 6% vs v2.3
Lattis Agent is listening
0:42
Routing policy
PROD
✓
Latency first
38 ms
✓
Fallback to eu-west
on
✓
Semantic cache
62% hits
Spend cap
$4k / day
Trusted by teams shipping AI in production
Northwind Labs
helio
QUORUM
Parcel
Veda Health
kestrel
WHY LATTIS
Most AI products stall between the demo and the deployment.Lattis is the layer in between: routing, sandboxes, evals and observability on one API, so your team ships the product instead of rebuilding the platform.
Three products built on one platform.
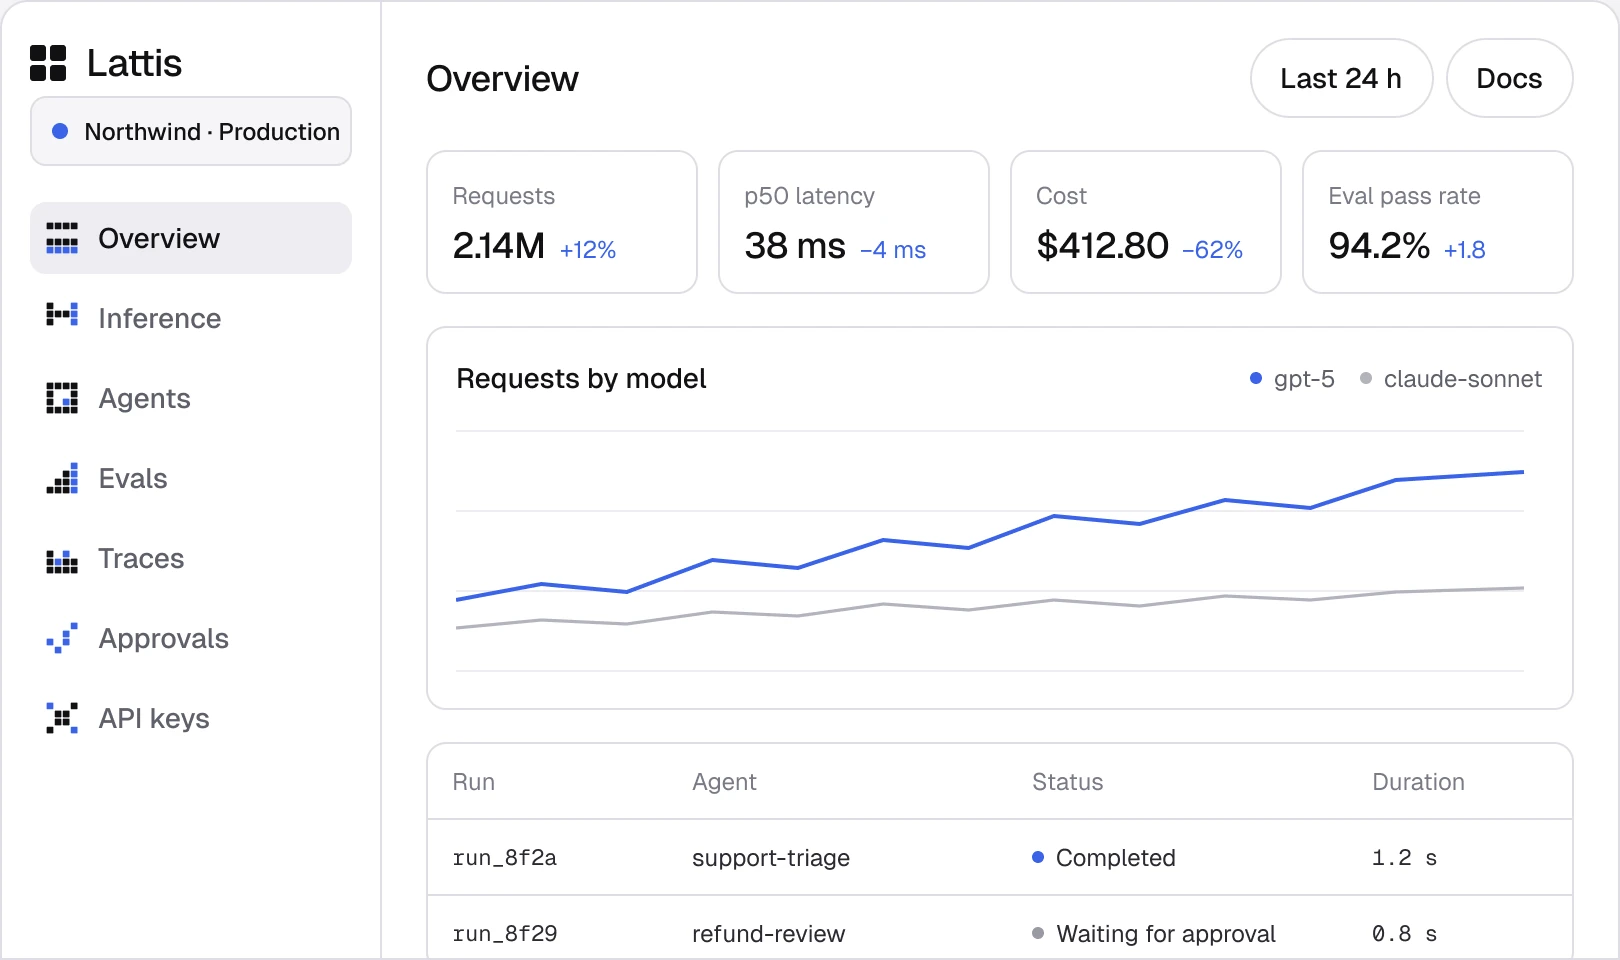
One console for routing, runs and quality. Every request, tool call and score lands in the same trace.


Lattis Inference
Serve any model behind one API.
140+ open and proprietary models, routed per request for quality, latency and cost. Swap models with a string and keep your code.

Caching
Semantic and exact caches cut repeat cost by up to 70%.

Streaming
Text, audio and vision streams through one interface.

Regions
11 regions with data residency pinned per API key.
Parcel
Handled Black Friday at 9x normal traffic on routed inference.
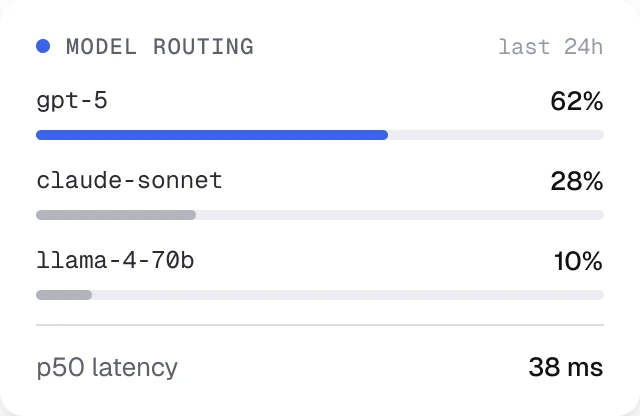
Smart routing
Send each request to the cheapest model that passes your quality bar.
Fallbacks
When a provider fails, traffic moves to the next model in under 50 ms.
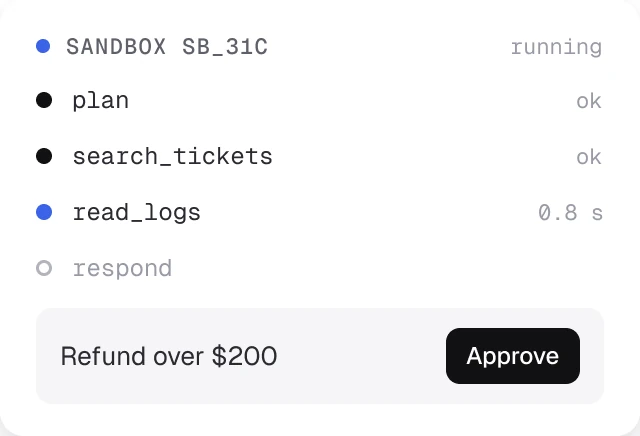
Persistent sandboxes
Filesystem and processes survive between steps for 24 hours.
Isolation
Every run gets its own container with network policy and secrets.
Lattis Agents
Run agents that stay inside the lines.
Isolated sandboxes, scoped credentials, streaming tool calls and a full audit trail for every run.

Tools
Any endpoint or function becomes a tool with a generated schema.

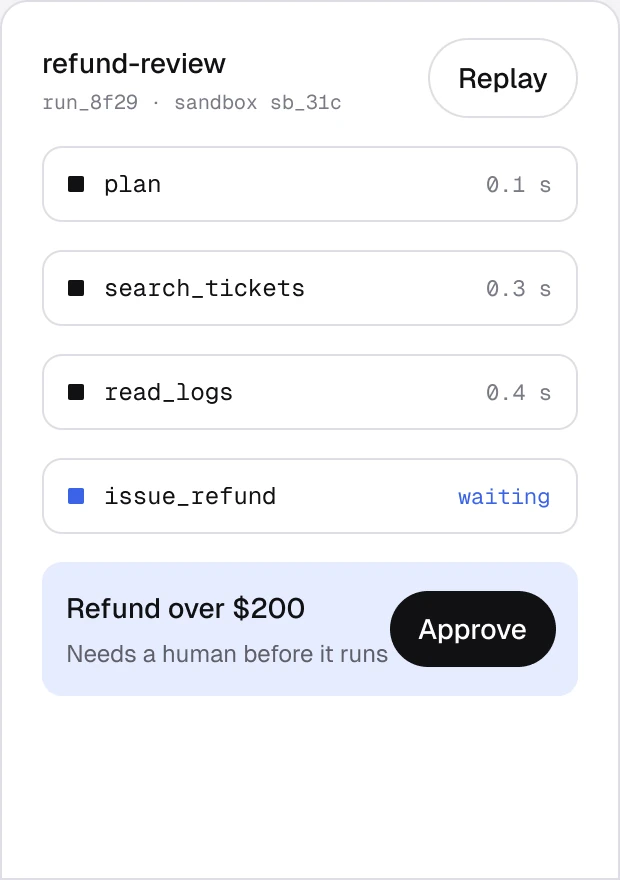
Approvals
Human sign-off on any step that touches money or data.

Replays
Step through any run with its exact inputs and outputs.
Osprey Finance
Automated 71% of tier-one support with approvals compliance signed off.
Or build on the API directly.
1
import{ Lattis } from"@lattis/sdk";
2
3
constclient = newLattis({ apiKey: process.env.LATTIS_API_KEY });
4
5
construn = awaitclient.agents.run({
6
agent: "support-triage",
7
input: "Customer reports a failed export",
8
tools: ["search_tickets", "read_logs"],
9
stream: true,
10
});
11
12
for await(const event of run) {
13
console.log(event.type, event.data);
14
}
2.1B
requests served per month
38 ms
median time to first token
99.99%
uptime, last 12 months
Security that passes your review.
Built for regulated teams from the first request. The security packet answers the questionnaire before you send it.
SOC 2 TYPE II
ISO 27001
GDPR
HIPAA-READY

Isolation
Every agent run in its own container.
Data residency
Pin each key to one of 11 regions.

Encryption
TLS 1.3 in transit, AES-256 at rest.

Access
SSO, SCIM, roles and an audit log.

Retention
Traces kept 30 days, down to zero.

No training
Your data never trains any model.
Pricing that scales with usage, not seats.
Developer
Free
Prototypes and side projects
- 1M tokens per month
- 100 sandbox minutes
- 3 agents
- Community support
Team
Most teams start here
$249
/ month
Products in production
- 50M tokens included, then usage
- 5,000 sandbox minutes
- Unlimited agents
- Evals with CI gate
Enterprise
Custom
Regulated and high-volume workloads
- Private networking and SSO
- Data residency per key
- Dedicated capacity
- 99.99% SLA
Usage beyond included amounts from $0.71 per 1M routed tokens. No platform fee until Enterprise.
Questions, answered.
The docs go deeper, or ask a solutions engineer.
Is my data used to train models?
No. Prompts, outputs and traces are never used to train models, ours or any provider’s. Traces are kept 30 days by default, configurable down to zero.
Which models can I use?
140+ open and proprietary models behind one endpoint, plus your own fine-tunes.
What counts as a routed token?
Input and output tokens, billed at the rate of the model that served the request. Routing itself is free.
Can I set a spend limit?
Yes, per key and per agent. Requests stop at the limit, and nothing is billed beyond it.
What happens when a provider has an outage?
Traffic moves to the next model in under 50 ms, with no code changes.
Is there a startup program?
Teams under two years old with less than $5M raised get Team free for 12 months.
Start with 1M free tokens.
No card required. Production keys in two minutes.