
The platform underneath your AI product.
Customer
Our checkout agent keeps timing out on big carts.
Lattis Agent
Found it. Big carts fall back to a slow region. Reroute them to eu-west?
Customer
Yes, go ahead.
✓ Resolved · 41 sec
Trusted by teams shipping AI in production
Everything between the prompt and production.
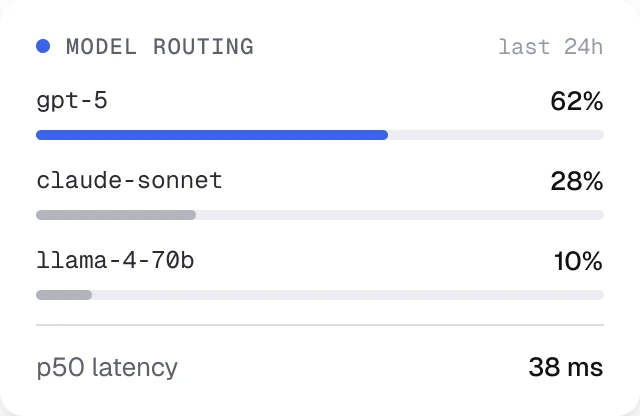
Five building blocks, one client. Pick the one you need today; the rest are already wired in.


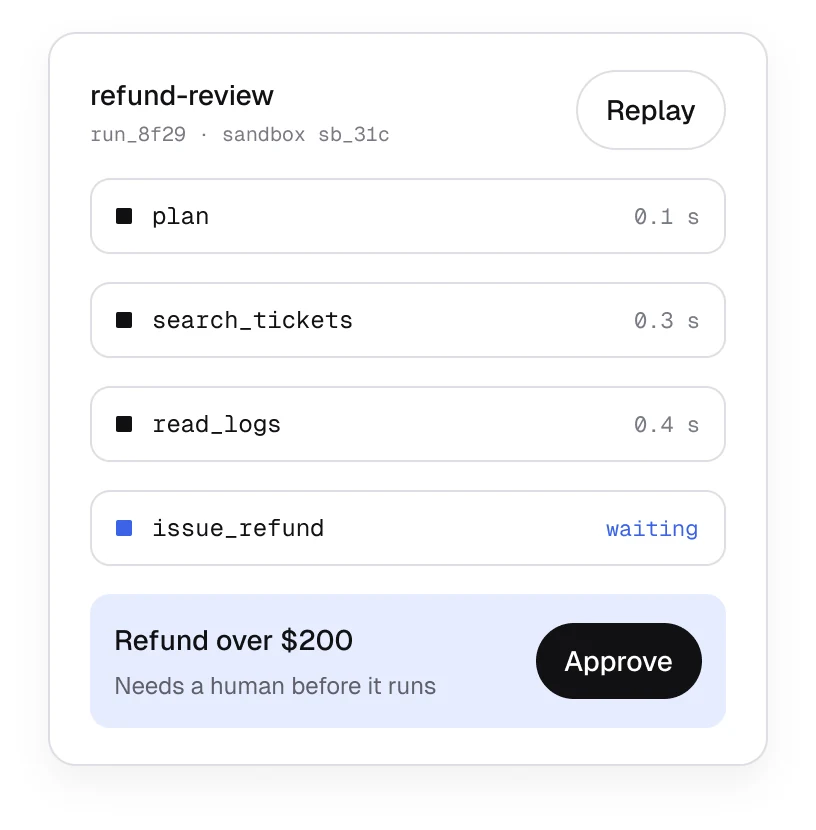
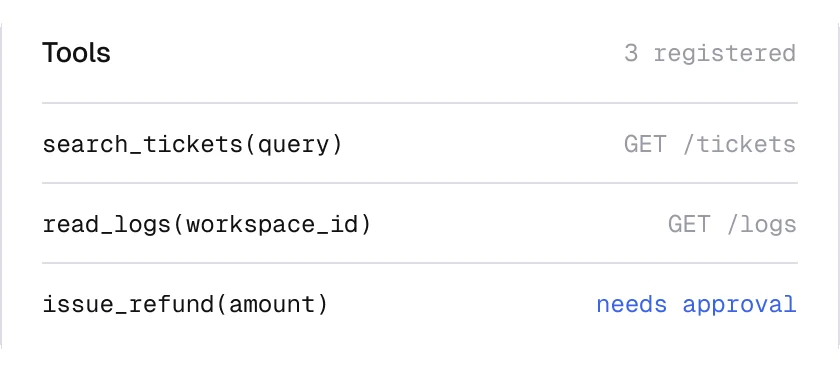
Your first agent in under five minutes.
Create an API key
Console, Keys, Create. Test keys start with lt_test_.
Install the SDK
Python, TypeScript or plain HTTP.
Run an agent
One call with an agent, an input and its tools.
Watch the trace
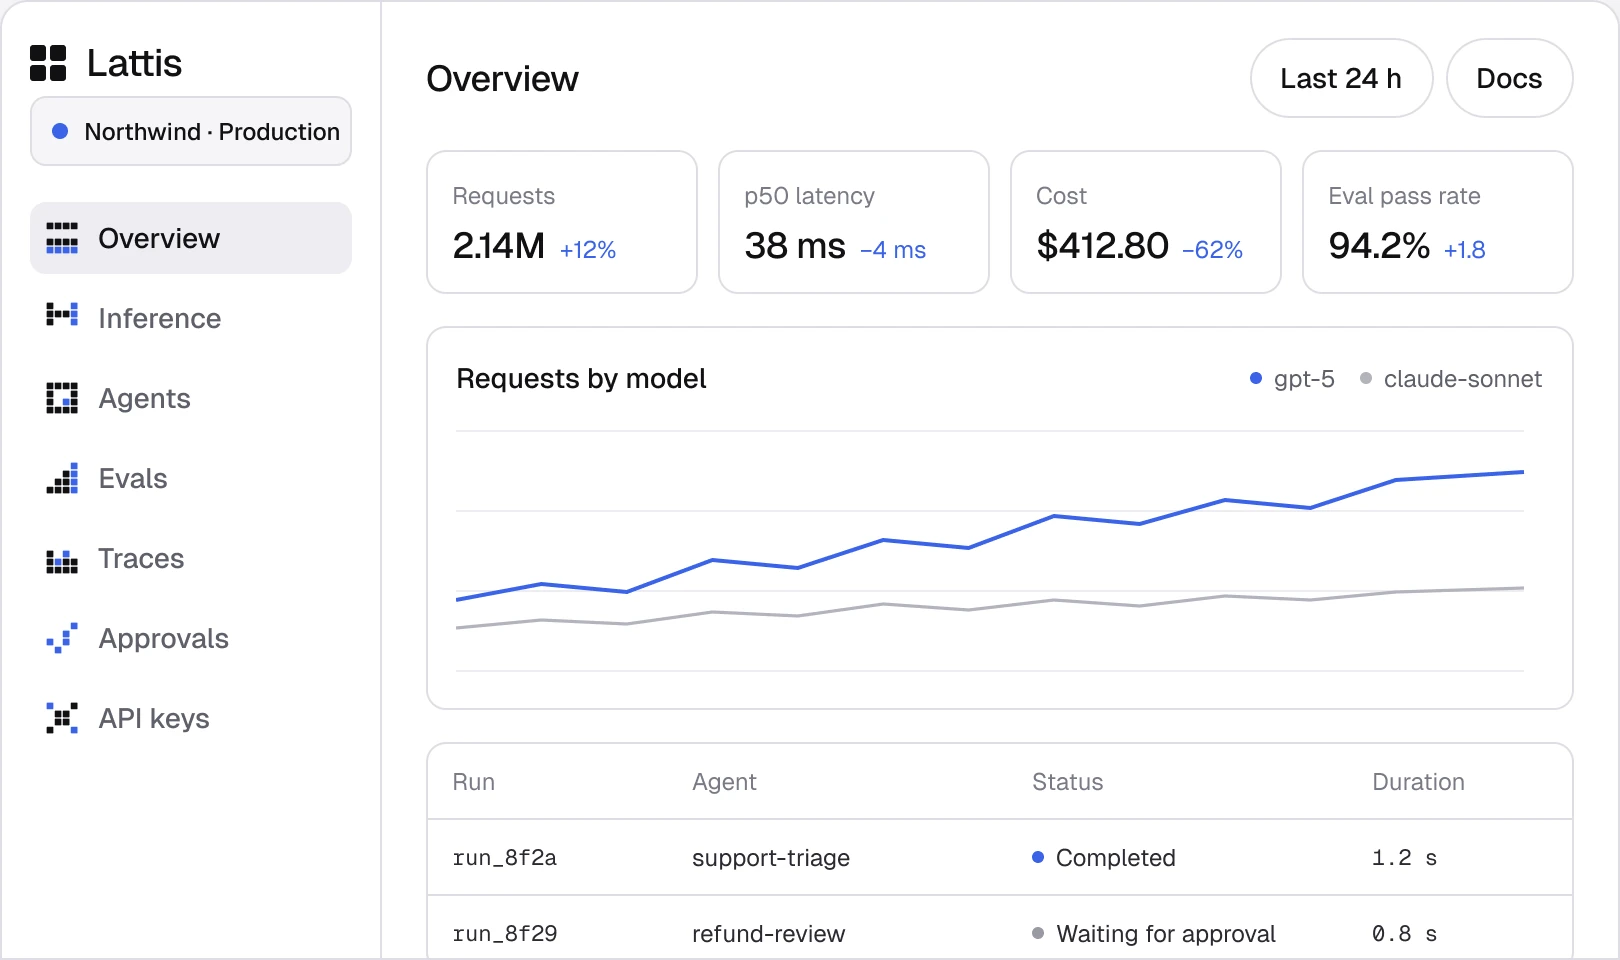
Every step, token and score in the console.
Plugs into the stack you already run.


Measured, not promised.
p50 across 1M production requests, September 2026. Methodology in the docs.
“Sandboxes gave us the thing we could not build ourselves: isolation we could explain to security.”
1.2M sandboxes a month, each in its own container with scoped credentials.
Your data never trains anything.
Isolation by default, encryption everywhere, and contracts that say so in writing. Built for teams that answer to auditors.
Isolation
Every run gets its own sandbox. Nothing is shared between tenants.
Encryption
AES-256 at rest, TLS 1.3 in transit, keys you can rotate.
Access
SSO, SCIM and role-based permissions for every project.
Retention
Zero data retention on request. Prompts never train a model.
Pay for tokens, not for seats.
Free up to 1M tokens a month. After that, routed tokens from $0.71 per 1M, billed monthly.
Routing itself is free. Spend limits stop usage per key and per agent.
1M tokens a month, 100 sandbox minutes, community support.
50M tokens included, 5,000 sandbox minutes, Evals with CI gate.
Private networking and SSO, dedicated capacity, 99.99% SLA.
We ship every week.
Streaming tool calls
Tool calls stream token by token, so your UI can render each step as it happens.
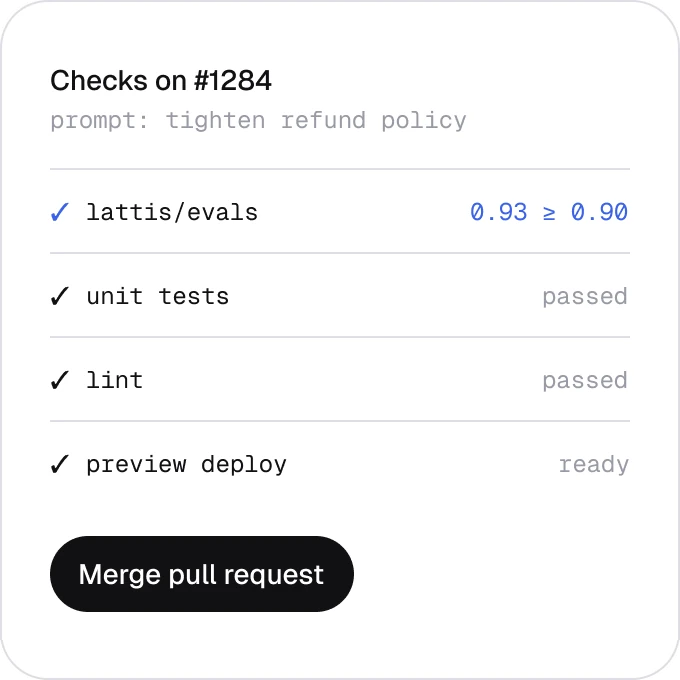
CI gate for GitHub Actions
Block a merge when a prompt change drops your eval score below threshold.
Semantic cache, gen two
Cache hit rate up 31% on repeated support and search traffic.
Frankfurt and Singapore
Pin data and inference to the EU or APAC with one project setting.
Developer questions, answered.
Not here? Ask in Discord or search the docs.
Which languages have an official SDK?
Python, TypeScript and Go, plus a REST API with an OpenAPI spec. Community SDKs cover Rust and Ruby.
Can I bring my own model weights?
Yes. Upload fine-tuned weights for supported open model families and Lattis serves them on dedicated capacity behind the same endpoint. Routing, caching and evals work the same way.
How are rate limits set per project?
Each project gets request and token limits per minute, set in the console or through the API. Add spend caps per key and per agent on top; limits apply before a request reaches a provider.
Do tool calls stream over WebSockets?
By default they stream over server-sent events, token by token, since v2.4. A WebSocket transport is available for agents that need two-way messages, such as approvals during a run.
Can I self-host the agent runtime?
On Enterprise, yes. The runtime deploys into your own VPC on Kubernetes while the control plane stays managed. Developer and Team plans run on Lattis cloud in the region you choose.
How do I move from Free to Team?
Open Billing in the console and choose Team. Your keys, agents and traces carry over, the 50M included tokens apply right away, and the first month is prorated.
Run your first agent in five minutes.
1M free tokens a month. No card, no sales call, production keys in two minutes.