The platform underneath your AI product.
One API for serving models, running agents and measuring quality. Ship in days, scale without rewriting.
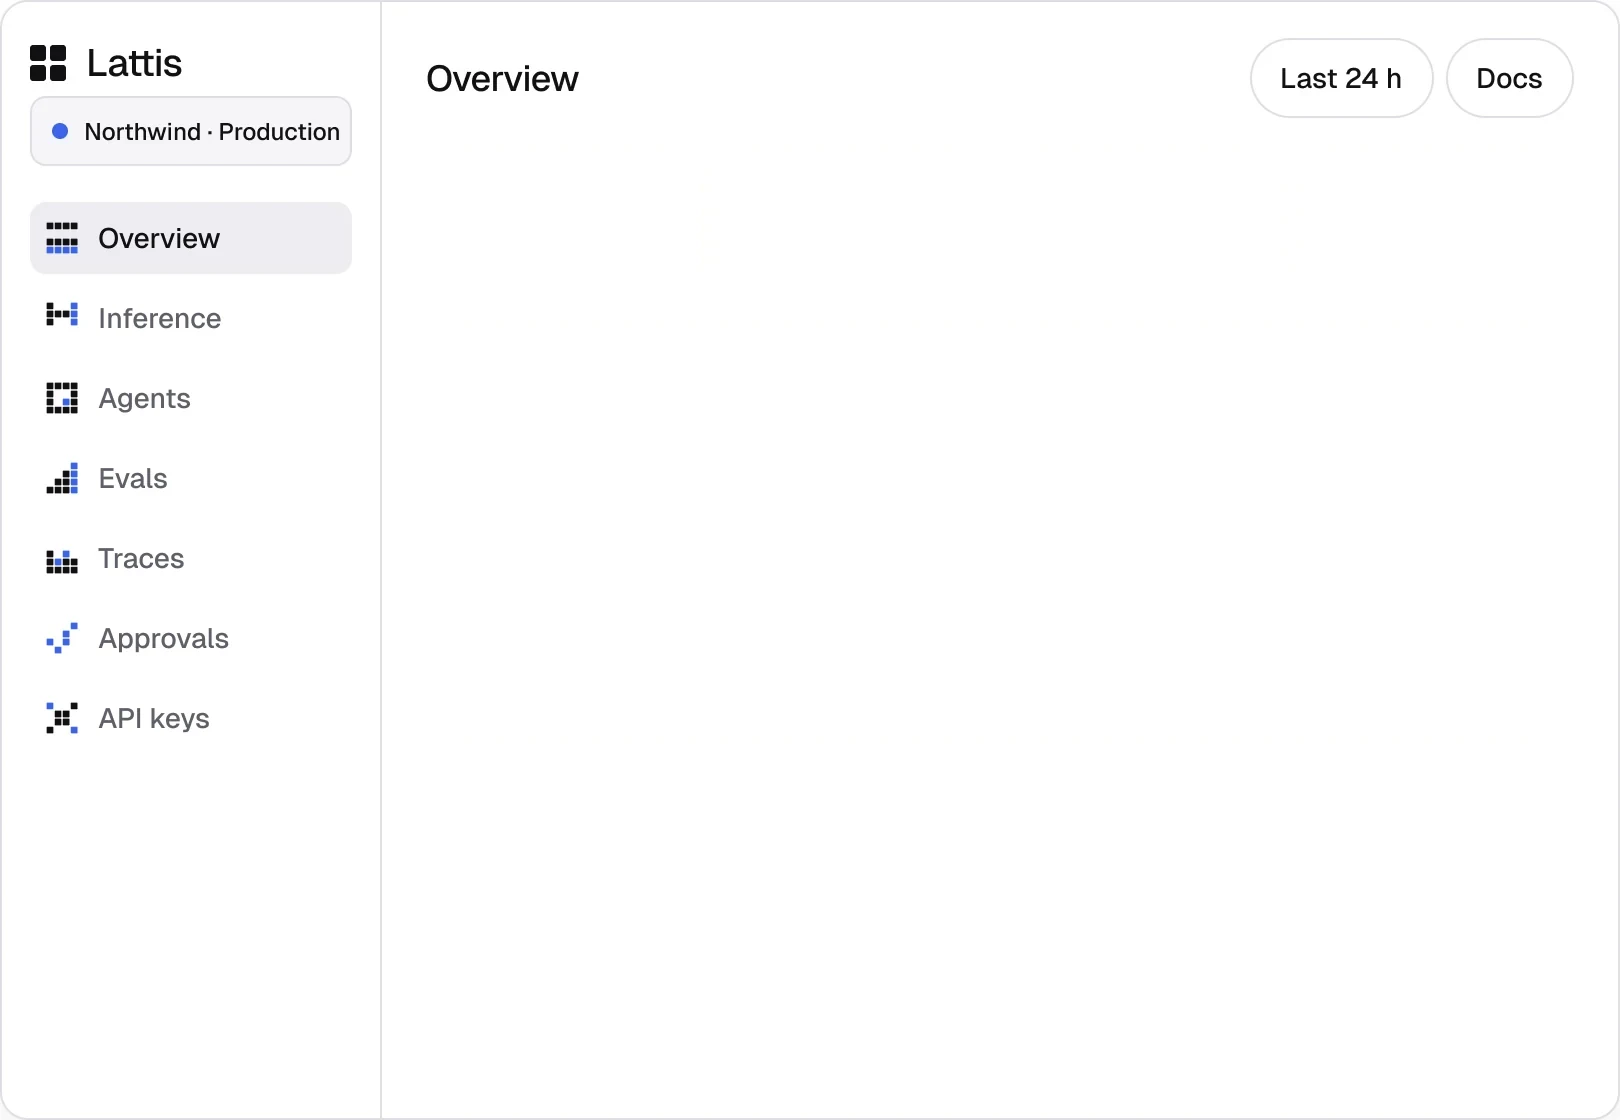
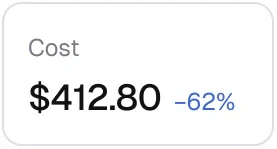
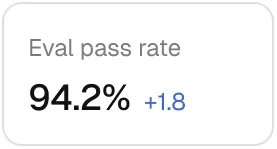



Teams that already closed the gap between demo and deployment.
Four principles we build by.
Written down in 2024, unchanged since. Every product decision gets checked against them.
Quality is a number.
If you cannot score it, you cannot ship it. Every change on Lattis is measured.
Models are interchangeable.
Your product should not be rewritten because a vendor changed its pricing.
Agents need walls.
Autonomy without isolation is an incident waiting to happen.
Cost is a feature.
The cheapest model that passes the bar is the right model.
Three products. One API.
Use one, or all three together. They share keys, traces and billing.
Serve any model, one API
140+ open and proprietary models, routed per request for quality, latency and cost.
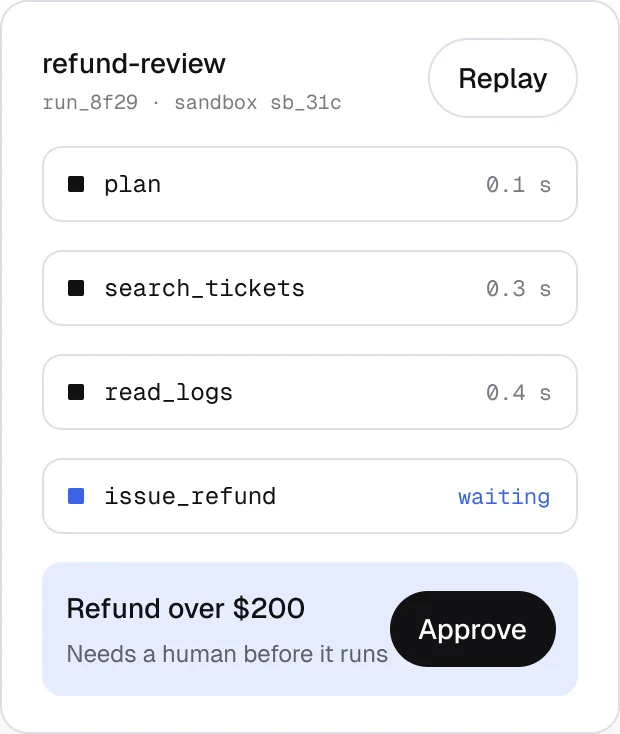
Agents that stay inside the lines
Isolated sandboxes, scoped credentials and streaming tool calls, with a full audit trail.
Know it is better before you ship
Rubrics, model graders and assertions on every change. Block the deploy that regresses.
Or build on the API directly.
One SDK for inference, agents and evals. Typed, streaming and versioned, with the same API in every region.
“We moved fourteen production agents in a week. The whole migration was a config change.”
Security is a principle, not a feature.
Built for teams that answer to auditors, from the first request.

Isolation
Per-run sandboxes. No shared memory between tenants.

Encryption
AES-256 at rest, TLS 1.3 in transit, your own keys.

Data residency
Keep data and inference in the US, EU or APAC.

Access
SSO, SCIM and roles scoped to each project.

Retention
Zero data retention available on every plan.

Audit log
Every model call and tool call, logged and exportable.
One platform, three ways to pay.
Start free and upgrade when traffic does. Every plan includes Inference, Agents and Evals.
Free
For side projects and prototypes.
$249 / mo
For teams shipping to production.
Custom
For regulated, high-volume teams.
Built by people who have run this at scale.
Fair questions, straight answers.
Which models can I use?
140+ open and proprietary models behind one endpoint, plus your own fine-tunes.
Do you train on our data?
No. Prompts and outputs never train a model, and zero retention is available on every plan.
How long does a migration take?
Most teams switch one endpoint in a day. The SDK is drop-in compatible with common client libraries.
Where is our data processed?
In the region you choose: US, EU or APAC. It never leaves that region.
What if a provider goes down?
Requests fail over to an equivalent model in under 200 ms, with no code changes.
Can we deploy in our own cloud?
Yes. Enterprise plans include VPC and on-premise deployment.
The platform underneath your AI product.
Start with 1M free tokens. No card required.